Why Security Teams Struggle to Reduce Alert Noise in 2026
Reducing alert noise means filtering out the flood of irrelevant, duplicate, and low-priority notifications so your team only sees alerts that actually need attention. Here’s how to do it:
- Deduplicate alerts – Consolidate repeated notifications about the same issue into a single alert
- Set smart thresholds – Use dynamic baselines instead of static triggers that fire on normal behavior
- Suppress low-priority noise – Mute non-critical alerts during maintenance windows or by priority level
- Correlate related events – Group alerts that share a root cause into one incident
- Enrich alerts with context – Add metadata so teams can triage faster without extra investigation
- Review and tune continuously – Schedule regular “alert gardening” to remove alerts that no longer serve a purpose
Your security team is drowning. Not in real threats — in noise.
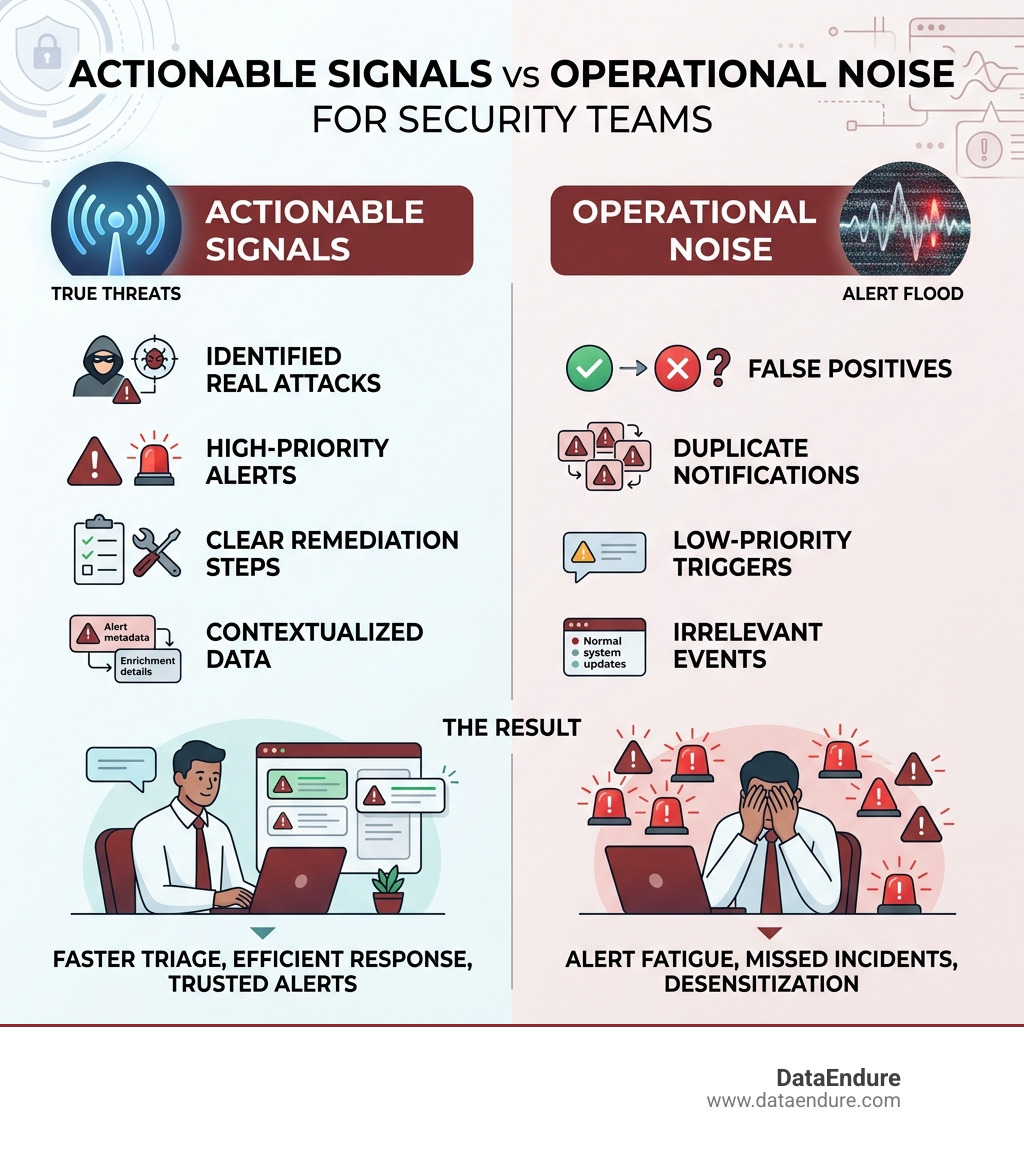
IT and cloud operations teams now receive thousands of alerts every single day. Studies suggest roughly 74% of those alerts are noise — false positives, duplicates, and low-priority triggers that don’t need human action.
That leaves your analysts wading through an enormous pile of irrelevant notifications just to find the ones that actually matter. And when everything looks urgent, nothing feels urgent.
This is especially dangerous if your organization has already experienced a breach. The last thing you need during recovery is a security team too exhausted and desensitized to catch the next real threat.
There’s a term for what happens to teams in this situation: alert fatigue. And it’s not just an inconvenience. Alert fatigue is widely recognized as the number one cause of missed incidents. When analysts stop trusting their alerts, real attacks slip through.
The good news? Alert noise is not an unsolvable problem. It’s actually a measurable one — and with the right strategies, teams have reduced their alert volume by as much as 90% without missing genuine threats.
This guide walks you through exactly how to get there.
The High Cost of Alert Fatigue in 2026
As we navigate the mid-2020s, the complexity of our digital environments has exploded. Between microservices, hybrid cloud architectures, and the constant hum of containerized applications in Silicon Valley data centers, the sheer volume of telemetry data is extraordinary. But more data hasn’t necessarily led to better security; often, it has just created a louder haystack in which to hide the needle.
In 2026, the cost of alert fatigue is no longer just a “line item” in an HR report about turnover. It is a primary operational risk. When we talk about what is threat detection in cybersecurity?, we are talking about the ability to identify malicious activity quickly. However, if your team is receiving 500 alerts a day and 400 of them are meaningless, your “detection” is effectively neutralized by volume.
The impacts of failing to reduce alert noise are severe:
- Missed Incidents: This is the “Boy Who Cried Wolf” syndrome. When an analyst sees the same “High CPU” or “Unusual Login” alert for the 50th time that day—and the previous 49 were false positives—they are statistically likely to ignore or “bulk-close” the 50th one, which might be the actual breach.
- Engineer Burnout: High-performing SREs and security analysts don’t want to spend their days clicking “dismiss” on redundant notifications. Constant context-switching destroys focus and leads to talented professionals leaving the industry.
- Increased MTTR: When a real incident occurs, the “noise” makes it harder to find the root cause. If a database failure triggers alerts across 50 dependent applications, the team has to sift through 51 alerts to find the one that actually matters.
- Financial Waste: Every minute an engineer spends triaging a false positive is a minute they aren’t spent on innovation or proactive security hardening.
Understanding what is the difference between EDR and SIEM? is a great starting point for visibility, but without a strategy to manage the output of these tools, you’re simply buying a faster way to generate noise.
Core Strategies to Reduce Alert Noise
To effectively reduce alert noise, we have to move beyond “gut-feel” tuning. It’s not about just turning off alerts until the screaming stops; it’s about a systematic engineering approach to signal quality. We treat alert configuration with the same rigor we treat application code—with reviews, testing, and continuous improvement.
There are three main layers to a modern noise-reduction framework:
- Mathematical Thresholds: Optimizing the “When” and “How much.”
- Correlation: Grouping related “pings” into a single story.
- Suppression and Enrichment: Silencing the known-safe and adding data to the unknown.
According to research, applying a multi-layered approach can reduce event noise by more than 90%. For example, some advanced correlation engines can even hit a 98% reduction rate by grouping alerts by common root causes.
Alert Suppression vs. Alert Tuning
| Feature | Alert Tuning | Alert Suppression |
|---|---|---|
| Goal | Improve the precision of the trigger logic. | Stop a notification from firing under specific conditions. |
| When to use | When a rule is fundamentally too broad or “chatty.” | During maintenance windows or for known-safe “flappy” alerts. |
| Result | Fewer alerts are created in the system. | Alerts are created (for forensics) but no one is paged. |
| Auditability | Changes the baseline detection. | Preserves the record without the distraction. |
For a deeper dive into these frameworks, check out Alert noise reduction: How to cut through the noise | BigPanda.
Implementing Deduplication to Reduce Alert Noise
Deduplication is often the “low-hanging fruit” of noise reduction. It addresses the scenario where a single failing check sends a notification every minute. If a service is down for an hour, you don’t need 60 emails; you need one alert that says “Service X is down” and perhaps a counter that shows it has failed 60 times.
We use alert keys or alias fields to accomplish this. By assigning a unique identifier to a specific problem (e.g., host-01-disk-space), the system can recognize that the second, third, and hundredth pings are all about the same issue. It “de-duplicates” them into a single incident.
When we help clients determine how do I choose a threat detection tool for my organization?, we always look for robust deduplication capabilities. Without it, your team is essentially being DDoS’d by their own monitoring system.
Using Suppression to Reduce Alert Noise
Suppression is the art of “knowing when to be quiet.” There are several scenarios where an alert might be technically “true” but operationally “useless.”
- Maintenance Windows: If our team in Santa Clara is performing scheduled upgrades on a server cluster, we don’t want the SOC to get 500 “Server Unreachable” alerts. Maintenance windows allow us to snooze notifications for a specific period while still logging the data for forensic review.
- Rule Snoozing: If a specific rule is being “noisy” due to a temporary configuration change, we can snooze that specific rule’s actions. This is better than deleting the rule entirely, as it ensures we don’t forget to turn it back on.
- Flappy Alerts: A “flappy” alert is one that toggles between “critical” and “resolved” every few seconds (like a CPU spike that hits 91% and then 89% repeatedly). We can use “auto-pause” or “delay” rules that only notify a human if the condition persists for, say, five minutes.
Research shows that simply moving a CPU alert duration from 1 minute to 5 minutes can suppress up to 91% of transient spikes. This is a massive win for reducing alert noise without increasing risk. For more on these mechanisms, see Reduce notifications and alerts | Elastic Docs.
Leveraging AIOps and Machine Learning for Precision
In 2026, static thresholds (e.g., “Alert me if CPU > 80%”) are increasingly obsolete. Modern environments are too dynamic for “one-size-fits-all” numbers. This is where AIOps and Machine Learning (ML) become essential.
Adaptive Baselines use ML to learn what “normal” looks like for your specific environment. For a Silicon Valley tech firm, “normal” network traffic at 2 PM on a Tuesday looks very different from “normal” at 2 AM on a Sunday. Instead of a flat line, the threshold becomes a “wave” that follows historical patterns. If traffic spikes outside that expected wave, that is an anomaly worth investigating.
Furthermore, SOAR and your security posture: 3 considerations for evaluating SOAR plays a huge role here. Automation can take an alert, perform the initial “triage” (like checking a file hash against a database), and only involve a human if the result is suspicious.
As we discussed in our May 2022 Tech Talk: Good, Better, Best – How well is automation supporting your security strategy?, the “Best” level of maturity involves self-tuning systems that adjust their own thresholds based on whether previous alerts were marked as “actionable” or “noise” by humans.
Measuring Success: Key Metrics for Operations Teams
You can’t manage what you don’t measure. To ensure we are actually reducing alert noise and not just silencing the system, we track several key performance indicators (KPIs):
- Actionable Rate: This is the most important metric. If you receive 100 alerts and only 10 required a fix or a ticket, your actionable rate is 10%. Your goal should be to drive this as high as possible.
- Mean Time to Acknowledge (MTTA): As noise goes down, MTTA should also go down. Analysts can respond faster when they aren’t buried under a mountain of junk.
- Mean Time to Resolve (MTTR): With better signal and context enrichment, teams can find the root cause and fix it faster.
- Alert Volume vs. Incident Volume: If your alert volume drops by 50% but your incident volume stays the same, you’ve successfully removed noise without missing threats.
When considering how do I choose a threat detection tool for my organization? (3), ensure the tool provides clear dashboards for these metrics. Success is seeing that “Actionable Rate” climb while your team’s stress levels drop.
Frequently Asked Questions about Alert Management
What is the difference between alert noise and alert fatigue?
Alert noise is a data quality problem—it refers to the high volume of irrelevant or redundant notifications generated by your systems. Alert fatigue is the human result of that noise—it’s the psychological exhaustion and desensitization that happens when security analysts are overwhelmed by notifications, leading them to miss real threats. Noise is the cause; fatigue is the consequence.
How can teams identify which alerts to remove?
A good rule of thumb is to look for “low-quality” alerts. New Relic and other industry leaders recommend removing or tuning alerts that:
- Open and close automatically in less than 5 minutes for more than 30% of events.
- Create more than 350 alert events per week.
- Have a cumulative “open duration” of thousands of minutes without any human action taken. If an alert fires and no one ever does anything about it, it’s noise.
What role does automation play in noise reduction?
Automation acts as a first-tier analyst. It can handle deduplication, correlate events across different silos (like matching a firewall log to an EDR alert), and enrich alerts with context from your CMDB. By the time a human sees the alert, automation has already filtered out the “junk” and gathered the evidence needed for a quick decision.
Conclusion
Reducing alert noise is not a one-time project; it is a continuous “gardening” process. In the environments of Santa Clara and the broader Silicon Valley, our infrastructure changes every day, and our alerting logic must evolve with it.
At DataEndure, we specialize in helping organizations move from “reactive chaos” to “proactive control.” Our managed cybersecurity solutions are built on the principle that rapid breach detection shouldn’t come at the cost of your team’s sanity. We use skilled experts and advanced AIOps to detect breaches in minutes, significantly reduce alert fatigue, and can deploy our framework in as little as 30 days.
By focusing on high-signal alerts and clearing away the operational noise, we empower your team to focus on what they do best: protecting your business.
Ready to clear the air? Strengthen your security posture with Zero Trust Micro-segmentation and see how a quieter SOC is a more effective one.